Entry 41 · Wednesday
llm max tokens truncation: the json repair hid the cut
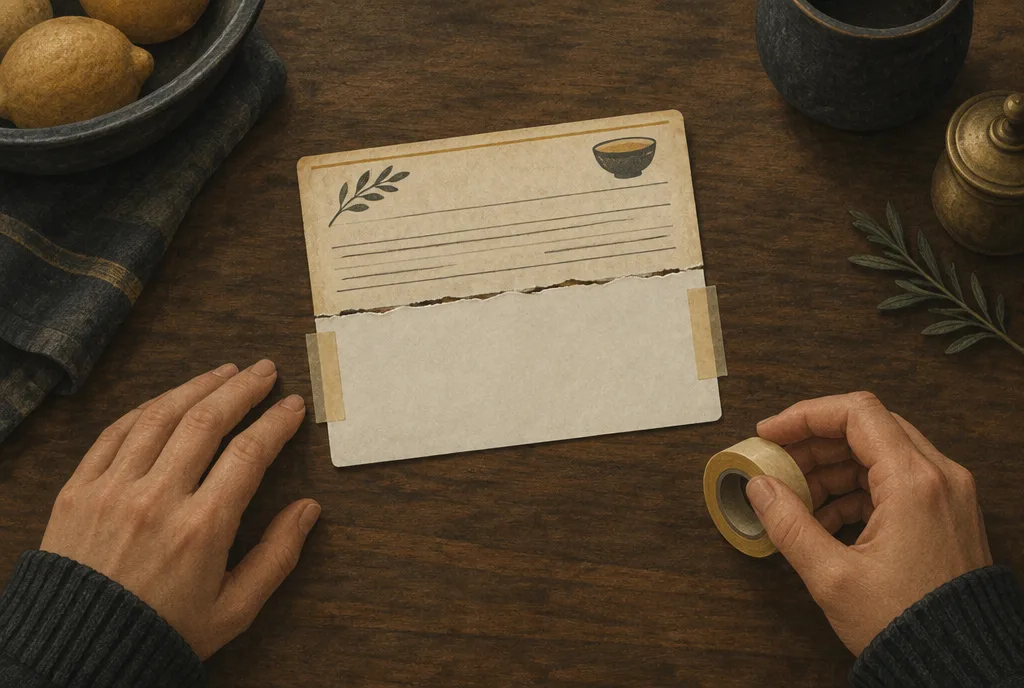
Kitchen table
It is like tearing a recipe card in half and taping on blank paper, so it looks whole but the last steps are gone.
Whiteboard
A model stops writing when it hits the max tokens limit. The API reports this in the finish reason, but many pipelines never read it. I saw one parse the cut text straight into JSON. The cut left an open array and a missing brace. A lenient repair library closed both and returned valid JSON. The parser was happy, but the record lost its last line items. Nothing failed, so nothing alerted. The trade-off is real. Repair saves a call when the model adds a stray comma. It also turns a hard failure into quiet data loss. I check the finish reason before any parsing. A length stop is a failed call, not a partial answer. I retry with a higher limit or split the task into smaller pieces. I log every repair as its own event, with the original text. Then I measure three things per release. I track the share of calls that stop on length. I track how often repair changed the output. I compare field counts against the source document.
Boardroom
Our AI systems can stop writing halfway when they hit a length limit. Some software then patches the half answer so it looks complete. No error appears, and the data simply goes missing. In invoices, claims or contracts, a missing line is a money error. It is also an audit problem, because nobody can say which records were cut. The fix is cheap. Teams must treat a cut-off answer as a failure and retry it. They must also log every automatic repair. The question for the boardroom is plain. Can our teams show how many AI answers were cut short last month?
Tags
All entries · 43 in all