Entry 37 · Saturday
llm context window truncation: the rules fell off the front
Kitchen table
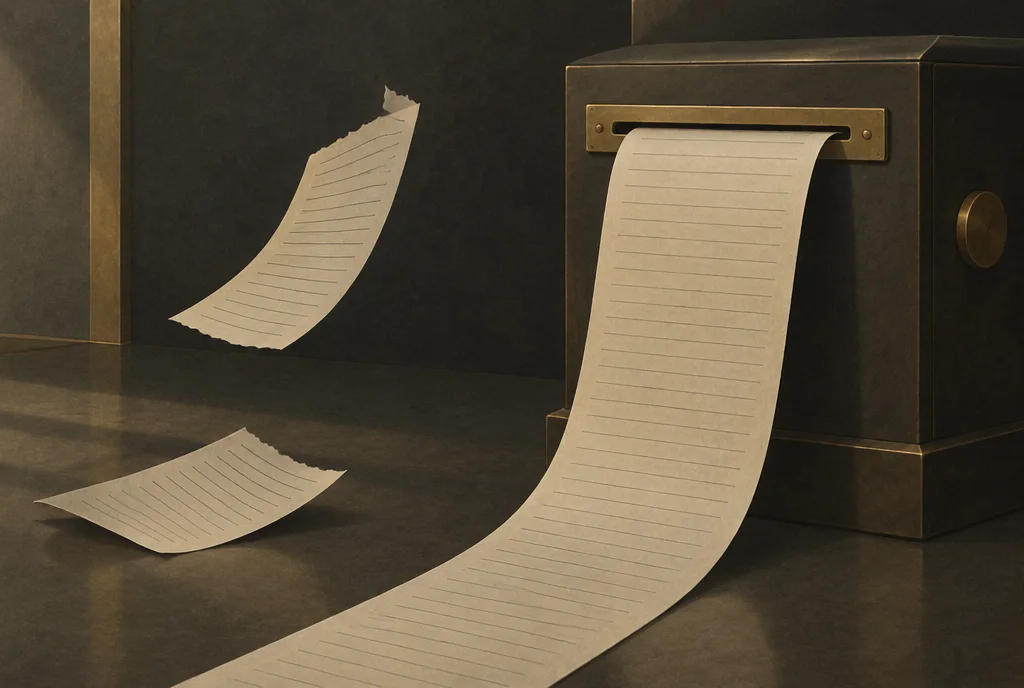
It is like a long note where someone tears off the top to fit the envelope, and the top said the rules.
Whiteboard
I see one quiet failure in long chat products. The conversation grows past the context window. Some layer then trims the input so it fits. Often it trims from the front, where the system prompt sits. So the rules vanish, and the model still answers fluently. Nothing errors, and the logs show a normal request. The trade-off is real, because trimming keeps the service up instead of failing the call. But position is the wrong way to choose what goes. I would trim by priority instead. Pin the system prompt and the current question, then summarise or drop the middle turns. Reserve room for the output before counting the input. Then measure it. Log input tokens, trimmed tokens and the trimming rule for every request. Alert when trimming touches a pinned block. Track rule adherence against conversation length. A flat line is healthy. A cliff at one length means something is cutting your instructions.
Boardroom
Our assistants can forget their own rules in long conversations. Nothing crashes, so nobody notices. The customer simply gets an answer that ignores policy. That is a compliance risk, not a quality blip. Long conversations are often the valuable ones, like complex claims or escalations. The fix is cheap engineering work, not a new model. Teams must decide what is never cut and watch when cutting happens. Ask your teams one question. When a conversation runs long, which instructions do we guarantee the model still sees?
Tags
All entries · 43 in all